One-way functions are easy to compute but it is very difficult to compute their inverse functions. Thus, having data x it is easy to calculate f(x) but, on the other hand, knowing the value of f(x) it is quite difficult to calculate the value of x.
There is not a mathematical proof that one-way functions . In practical applications functions that behave similarly as real one-way functions are used.
One-way functions are key elements of various tools useful in modern cryptography. They are used in pseudorandom generators, authentication of messages and digital signatures.
Trapdoor one-way function
Trapdoor one-way functions are types of one-way functions that contain a kind of "back door" (trapdoor). As in the case of ordinary one-way functions it is easy to compute their values for given data but it is very difficult to compute their inverse functions. However, if one has some additional secret information, he can easily compute the inverse function as well.
An example of such trapdoor one-way functions may be finding the prime factors of large numbers. Nowadays, this task is practically infeasible. On the other hand, knowing one of the factors, it is easy to compute the other ones.
One-way hash function
One-way hash functions (there are a lot of of functions of this type) transform input messages of various length into output sequences of fixed length (usually shorter). The output sequence is often called a hash value. Hash values are often used to mark input sequences, that is to assign to them some unique values that characterize them.
One-way hash functions fulfil all conditions of one-way functions. It is easy to compute their values based on input data but having only a hash value one can't determine the original input sequence.
A one-way hash function should be collision-free. This means that it should be very difficult to find two different sequences that produce .
Algorithms of one-way hash functions are often known to the public. They provide security thanks to their properties as one-way functions. Usually, a change of one bit of input data, causes changing about half of the output bits. Data generated by hash functions should be pseudorandom (it cannot be possible to distinguish output data from ordinary random data).
One-way hash functions are used to protect data against intentional or unintentional modifications. Having some data, one can calculate a checksum that may be attached to the message and checked by other recipients (by computing the same checksum and compare it with the received checksum value). They are used for example in a message authentication algorithm HMAC.
Moreover, hash functions are used for storing data efficiently, in so-called hash tables. Data can be accessed by finding hash values, which are stored in computer memory.
Hash function expanding
Having a hash function that operates on small blocks of data, one can expand this function and create a new function that operates on larger input data of various sizes. In such a way it is possible to compute a hash value for any messages. To achieve this, one can use so called Merkle-Damgard construction.
A scheme below presents a way of using multiple hash functions (h: T x X → T, where T is a set of all possible hash values) that allows to compute a hash value for the whole message (H: XL → T). Each hash function operates on one data block.
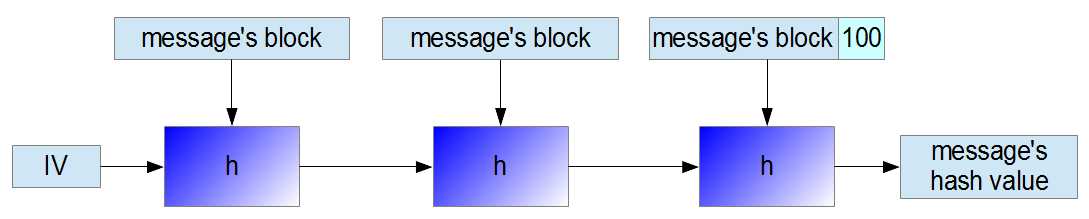
The first h function is initialized by a previously determined vector IV. The last data block should be fulfilled to the full-length using previously agreed bits. A popular method of aligning the length of the last block is about appending an additional bit equal to 1 and then filling the rest of the block with bits equal to 0. It allows to determine precisely the end of the real message.
It may be proved that if the function h is collision-free, then the function H (which is created based on functions h) is also collision-free. Every collision in the function H would automatically result in a collision in the function h.
Hash functions based on block ciphers
There are a few popular ways of creating one-way hash functions, that operate on input data of various lengths, using algorithms of block ciphers.
The Davies-Meyer hash function (denoted h) uses the encryption algorithm E that operates on subsequent data blocks:
h(H, m) = E(m, H) XOR H
A scheme of Davies-Meyer function is presented below:
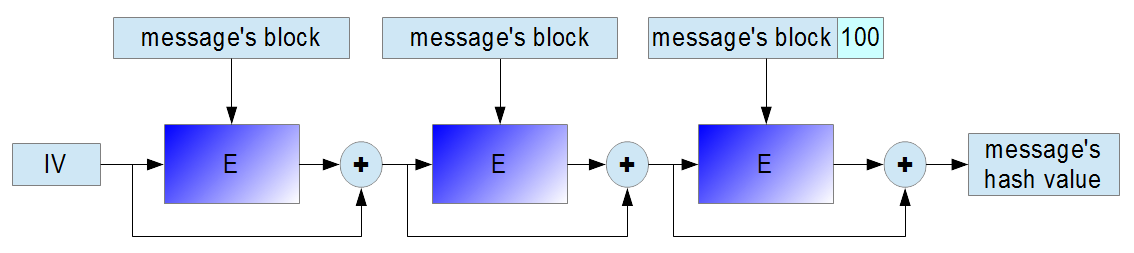
It can be proved that if E is a secure algorithm of a block cipher, then an intruder would have to perform about O(2n/2) encryption operations to find a collision (thus, to find a message with the same hash value as the hash value that he would like to find).
Another kind of hash functions based on block ciphers are Miyaguchi-Preneel functions. There are 12 kinds of those functions, for example:
h(H, m) = E(m, H) XOR H XOR m
or:
h(H, m) = E(H XOR m, m) XOR m
The proving of existence of one-way functions would prove that the complexity classes nondeterministic polynomial (NP) and deterministic polynomial (P) are not equal. This is one of the most important questions of theoretical computer science.
One-way hash functions are also referred to as contraction functions, compression functions, message digest, fingerprint, cryptographic checksum, message integrity check (MIC) and manipulation detection code (MDC).
Compression functions change a fixed-length input into a fixed-length output. They are often used in cryptographic algorithms, for example in block ciphers.
According to the birthday paradox (or birthday problem) a collision would be discovered after checking the amount of messages equal to the square root of all possible messages, using simple brute force attacks.
This significantly reduces time that is needed to find repeated values of hash functions. While designing hash functions one should consider this property. For example, to break the SHA-256 function one should check about 2128 messages, thus it may be considered to be relatively secure.